Implementation Details
In many ways, Zephyr provides support like any POSIX OS; API bindings are provided in the C programming language, POSIX headers are available in the standard include path, when configured.
Unlike other multi-purpose POSIX operating systems
Zephyr is not “a POSIX OS”. The Zephyr kernel was not designed around the POSIX standard, and POSIX support is an opt-in feature
Zephyr, libraries, and application code are compiled and linked together into one artifact, running by default like a single-process application, in a single (possibly virtual) address space
Processes are opt-in: with POSIX_MULTI_PROCESS, a process is a kernel thread group, additional process images are prelinked into the same artifact or loaded from the file system as ELF extensions, and
fork()duplicates an address space where the hardware supports it (see Multi-Process Design)Zephyr does not provide a POSIX shell, compiler, utilities, and is not self-hosting.
Note
Unlike the Linux kernel or FreeBSD, Zephyr does not maintain a static table of system call numbers for each supported architecture, but instead generates system calls dynamically at build time. See System Calls for more information.
Design
As a library, Zephyr’s POSIX API implementation makes an effort to be a thin abstraction layer between the application, middleware, and the Zephyr kernel.
Some general design considerations:
The POSIX interface and implementations should be part of Zephyr’s POSIX library, and not elsewhere, unless required both by the POSIX API implementation and some other feature. An example where the implementation should remain part of the POSIX implementation is
getopt(). Examples where the implementation should be part of separate libraries are multithreading and networking.When the POSIX API and another Zephyr subsystem both rely on a feature, the implementation of that feature should be as a separate Zephyr library that can be used by both the POSIX API and the other library or subsystem. This reduces the likelihood of dependency cycles in code. When practical, that rule should expand to include macros. In the example below,
libposixdepends onlibzfoofor the implementation of some functionality “foo” in Zephyr. Iflibzfooalso depends onlibposix, then there is a dependency cycle. The cycle can be removed via mutual dependency,libcommon.

Dependency cycle between POSIX and another Zephyr library

Mutual dependencies between POSIX and other Zephyr libraries
POSIX API calls should be provided as regular callable C functions; if a Zephyr System Call is needed as part of the implementation, the declaration and the implementation of that system call should be hidden behind the POSIX API.
Organization and Source Layout of POSIX Options and Option Groups
IEEE Std 1003.1 defines POSIX
Options
and
Subprofiling Option Groups
separately. Zephyr maps each standard Option Group to a directory under lib/posix/.
When an implementation supports an Option Group (or an Option), it is required to define a constant
to indicate support for that Option Group (or Option) for C source files. For example, if the
implementation supports the POSIX_TIMERS Option Group, it is required to define the macro
_POSIX_TIMERS to a specific value. In most cases, the Option Group names and the associated Option
(and macro) names differ by only one character (the prefixing underscore).
However, some Options and Option Groups are intentionally not published as Subprofiling Option Groups because they do not meet the criteria established by IEEE Std 1003.13. Namely, that Subprofiling Option Groups must
have a minimal footprint - to facilitate specialized, embedded, resource-constrained target devices, and
independence - to decouple functionality from other Options and Subprofiling Option Groups.
See also POSIX Application Environment Profiles (AEP) for how Zephyr maps PSE51/52/53 choices onto individual Kconfig options.
For example, the XSI_REALTIME Option Group and the _POSIX_MESSAGE_PASSING depend on other Options or Option Groups (POSIX_DEVICE_IO, POSIX_REALTIME_SIGNALS, etc) and therefore are not qualified to be standard Subprofiling Option Groups.
For simplicity and maintainability, Zephyr organizes such Options and Option Groups the same as
standard Subprofiling Option Groups (at the discretion of the maintainer), under
lib/posix/.
The general rule is that Option Groups will always have an associated Kconfig option and some Options (but not all) have an associated Kconfig option in Zephyr. The latter is mostly for maintainability.
OS-dependent and OS-independent functions
Not every POSIX function needs an operating system. The C library implements the
OS-independent ones: string and memory functions, character classification, qsort(),
strtol(), the printf() family’s formatting, getopt(), regcomp(), and so on.
They are pure library code, the same on every system, and each of Zephyr’s C libraries (the
minimal libc, newlib, picolibc, or the host libc on native_sim) ships its own.
The OS-dependent functions are the ones that touch kernel state: threads and scheduling,
mutexes and condition variables, clocks, timers and sleeps, signals, file descriptors, files and
directories, sockets, memory mappings, processes. On a self-hosted system the C library
implements these over the kernel’s system calls. On Zephyr, posix-next implements them in
lib/posix/<option_group>/ over Zephyr system calls, one directory per
Option Group, and the C library’s headers declare them.
Which side provides a function is not fixed by the standard but by the toolchain. A C library
that ships its own implementation of an Option Group, a libc with its own pthreads for example,
declares it with CONFIG_TC_PROVIDES_POSIX_THREADS and the other
CONFIG_TC_PROVIDES_<OPTION_GROUP> symbols, and posix-next then omits its own; the
remaining groups come from the module. This is also how the host libc is used unmodified by the
linux_compat test configurations on native_sim.
Overriding C library functions
A C library is a static archive, and the linker extracts an archive member only to satisfy a
symbol that is still undefined. A function defined in an object file of the application, or in
any library linked before libc.a, is therefore already defined when the archive is searched,
and the library’s own copy is never pulled in. No flag is needed: with gcc on Linux,
pthread_create() #include <pthread.h>
#include <stdio.h>
int pthread_create(pthread_t *thread, const pthread_attr_t *attr,
void *(*start)(void *), void *arg)
{
/* create the thread with the clone() system call ... */
printf("pthread_create() succeeded\n");
return 0;
}
$ gcc -o foo main.c mypthread.c -lc
$ ./foo
pthread_create() succeeded
The same rule applies in Zephyr: application and module objects are linked before the C
library, so a definition in them overrides the library’s. posix-next relies on it for the
OS-dependent functions that a prebuilt libc also contains, sysconf() in full newlib for
instance. Three things to keep in mind:
The replacement is called by code inside the library too, with the library’s own ABI. A prebuilt newlib calls
sysconf(_SC_PAGESIZE)frommalloc()with its value of the constant, so the replacement must agree with the headers the library was built against, not with a private numbering.Only calls through the public symbol are redirected. Internal entry points keep their own names (newlib’s reentrant
_write_r()is notwrite()), and a library built with internal aliases or link-time optimisation may bypass the public name entirely.When the original must stay reachable, link with
-Wl,--wrap=nameinstead: calls tonamego to__wrap_nameand the original is available as__real_name. In Zephyr,zephyr_link_libraries(-Wl,--wrap=name)adds the flag.
Non-Portable Extensions
Beyond IEEE Std 1003.1, Zephyr provides a small set of extensions that programs written for
other Operating Systems, such as Linux or BSD, commonly rely on. Each follows the existing
convention, so that compatible programs build and behave as expected, and the linux_compat
twister variants run the corresponding testsuites against the host libc to keep the two in
step. Extensions that share a header with standard interfaces are only visible when the
program asks for them, by defining _GNU_SOURCE (or _BSD_SOURCE) before the first
include.
POSIX_NON_PORTABLE
POSIX_NON_PORTABLE (CONFIG_POSIX_NON_PORTABLE) collects
the _np pthread functions that <pthread.h> declares under _GNU_SOURCE. Like every
other pthread function they operate on the k_thread behind the pthread_t (see Native
POSIX Thread Library below), so they are available to unprivileged threads that hold
permission on the thread object.
pthread_setname_np()andpthread_getname_np()read and write the kernel thread name (CONFIG_THREAD_NAME, selected by the option group).pthread_tryjoin_np()andpthread_timedjoin_np()are the conventional non-blocking and absolute-deadline (CLOCK_REALTIME) forms ofpthread_join(); a NULL deadline blocks indefinitely.pthread_setaffinity_np()andpthread_getaffinity_np()are thin wrappers over the kernel’s per-thread CPU mask,k_thread_cpu_mask_set()andk_thread_cpu_mask_get(), which exist withCONFIG_SCHED_CPU_MASK; the option group implies it wherever the scheduler backend supports it.cpu_set_tand theCPU_*macros come from<sched.h>or<pthread.h>under_GNU_SOURCE, name CPUs by index up toCPU_SETSIZE, and are mapped onto the kernel mask by index. The whole mask is replaced in one step, so a thread is never momentarily left without a CPU, and a runnable thread whose new mask excludes the CPU it is on is handed back to the scheduler and picked up by a permitted CPU; that includes the calling thread, which returns on a CPU named by the new set. CPUs that do not exist are ignored, but at least one existing CPU must remain (EINVAL). WithoutCONFIG_SCHED_CPU_MASKevery thread runs on every CPU, so the getter reports the full set and the setter accepts only that set, returningENOTSUPfor anything narrower; withCONFIG_SCHED_CPU_MASK_PIN_ONLYa set may name only one CPU and a runnable thread cannot be moved, matching the kernel’s rules for that variant.
Event file descriptors
<sys/eventfd.h> (CONFIG_EVENTFD) provides eventfd(),
eventfd_read(), eventfd_write(), eventfd_t, EFD_NONBLOCK and
EFD_SEMAPHORE with the conventional semantics: a 64-bit counter that write() adds
to and read() returns and resets, or decrements by one in semaphore mode, with
EAGAIN in place of blocking when non-blocking. The descriptor is an ordinary ZVFS file
descriptor (CONFIG_ZVFS_EVENTFD_MAX bounds their number), so it also works with
poll(), select(), close(), and as a target of asynchronous I/O, where
it counts as a descriptor with a waitable readiness condition (see
_POSIX_ASYNCHRONOUS_IO).
Other compatible extensions
SIGEV_THREAD_IDwith the conventionalsigev_notify_thread_idfield instruct sigeventletstimer_create(),mq_notify()and the asynchronous I/O functions direct their notification signal at a specific thread. Zephyr’s own headers declare it, and the patched picolibc and newlibstruct sigeventcarry the field as well.fnmatch()accepts the GNU flagsFNM_LEADING_DIR,FNM_CASEFOLD(aliasFNM_IGNORECASE) andFNM_EXTMATCHunder_GNU_SOURCE.MSG_NOSIGNALis accepted bysend()and friends with its conventional meaning.getenv_r()(_BSD_SOURCE) is the conventional reentrant form ofgetenv(), reading an environment variable into a caller-supplied buffer.
The posix Zephyr shell command (CONFIG_POSIX_SHELL) is tooling rather than
API: its env and uname subcommands expose the environment and uname() output
from the shell.
Native POSIX Thread Library (NPTL)
Zephyr’s POSIX threading implementation follows the same threading model as the
Native POSIX Thread Library (NPTL)
found in glibc on Linux: threading is strictly 1:1, with no user-space scheduler or M:N
multiplexing layer — each pthread_t is a k_thread. The synchronization primitives
follow NPTL too: each pthread_mutex_t is a sys_mutex and each
pthread_cond_t is a sys_condvar, futex-based objects in user memory shared
with the C11 mtx_t and cnd_t and with the C library’s own locks, entering the kernel
only on contention (see below).
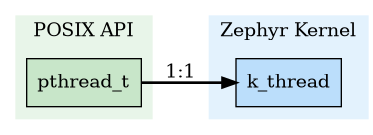
1:1 mapping between POSIX and Zephyr kernel objects
pthread_t is an opaque integer handle whose value is derived from the address of the
underlying kernel object in a system-wide pool. The conversion is performed by to_k_thread()
(and its inverse) defined in the internal header posix_internal.h.
This 1:1 design means:
No extra scheduling layer — every POSIX thread is a kernel thread (and vice versa)
Kernel-level visibility — debuggers and trace tools see the same objects as the application.
Full userspace support — thread operations bottom out in a Zephyr system call operating on a kernel object, and mutexes and condition variables live in user memory, so the POSIX threading API is available to both privileged and unprivileged (userspace) threads. As with everything userspace, it is important to keep in mind that user threads do not have permission on any kernel objects by default.
POSIX is optional - POSIX is entirely optional in Zephyr. However, in order to use POSIX features, it is highly recommended to enable one of the POSIX subprofiles such as
CONFIG_POSIX_AEP_CHOICE_PSE51.
Mutexes and condition variables
pthread_mutex_t is Zephyr’s sys_mutex and pthread_cond_t is Zephyr’s
sys_condvar: futex-based objects in user memory (backed by k_futex), so that the
uncontended lock and unlock fast paths complete with a single atomic operation and no system
call, entering the kernel only to block (k_futex_wait()) or to wake a waiter
(k_futex_wake()). The same objects implement the C11 mtx_t and cnd_t and the C
library’s own locks, so the mutex attribute layer of POSIX is the only thing the POSIX module
adds: the type and protocol of a pthread_mutexattr_t become the options the object is
initialized with, and PTHREAD_MUTEX_INITIALIZER is a sys_mutex of type K_MUTEX_NORMAL.
The mutex word follows the classic three-state scheme (unlocked, locked, locked with possible
waiters); the condition variable pairs a sequence word with the count of blocked waiters that
the kernel maintains in every k_futex, so that a signal or broadcast with no waiter costs
no system call at all, a signal wakes exactly one blocked waiter, and a woken waiter never
touches the object again, which makes destroying a condition variable right after a broadcast
safe. PTHREAD_MUTEX_ERRORCHECK and PTHREAD_MUTEX_RECURSIVE mutexes record their owner
in user memory. A PTHREAD_PRIO_INHERIT mutex is backed by a kernel mutex that the kernel
associates with the address of the user object, never with its contents: every operation on it
is a system call, ownership is enforced by the kernel, and the owner inherits the priority of
the highest-priority waiter (CONFIG_SYS_MUTEX_PRIO_INHERIT, selected by
CONFIG_POSIX_THREAD_PRIO_INHERIT). Because the futex system calls are
building blocks rather than POSIX interfaces, they are not cancellation points:
pthread_cond_wait() tests for a pending cancellation while the mutex is still held, as
POSIX requires, and pthread_mutex_lock() never acts on one. With
CONFIG_THREAD_CANCEL_TLS that test reads a copy of the pending flag in
thread-local storage and only enters the kernel when a cancellation is actually pending.
A thread created with pthread_create() starts with cancellation enabled whatever its
creator’s signal mask: a kernel thread masks every signal, the cancellation signal included,
and a thread it creates would otherwise never act on pthread_cancel().
A futex word is usable by every thread that can write its memory, so the trust boundary of a
mutex or condition variable is the memory domain (a process, or explicitly shared memory for
PTHREAD_PROCESS_SHARED objects) rather than per-thread kernel object permissions. The kernel
itself remains protected in either case, since the futex system calls validate the caller’s
access to the futex word. The mechanism needs no MMU or MPU, only atomic operations; on
platforms that fall back to CONFIG_ATOMIC_OPERATIONS_C every user-mode atomic operation is
itself a system call, so the uncontended path is not free there.
Thread-specific data
A pthread_key_t is a kernel thread-specific storage key, and a value is a kernel association
between the key and the thread, kept on the key’s list and on the thread’s list under one lock.
pthread_key_delete() drops every value still associated with the key, in any thread,
without calling the destructor, and the key is free for reuse at once. A thread that exits pops
its remaining values and calls the destructor of each non-NULL one; a destructor may store a
value again, so the passes continue, each visiting the values stored when it started, for at
most CONFIG_THREAD_SPECIFIC_STORAGE_DESTRUCTOR_ITERATIONS passes, which
PTHREAD_DESTRUCTOR_ITERATIONS reports; the values left after that are dropped. Cleanup handlers run before the destructors, and both run in the exiting thread’s
own context and privilege level.
Scheduling Priorities
POSIX and Zephyr order their scheduling priorities in opposite directions. POSIX priorities
are non-negative and numerically larger is more urgent: each policy advertises its range
through sched_get_priority_min() and sched_get_priority_max(). Zephyr’s
native priorities are numerically smaller is more urgent: cooperative threads occupy the
negative values and preemptible threads the non-negative ones.

Zephyr’s native priority axis. POSIX priorities map onto it reversed, so the POSIX maximum for a policy corresponds to the most negative (leftmost) Zephyr value in that policy’s band.
The POSIX layer converts exactly once, at its boundary: pthread_setschedparam(),
sched_setscheduler(), and friends map a POSIX priority into the Zephyr band for the
requested policy, and everything below the boundary works exclusively in Zephyr’s native
space.
This is why prioritized I/O orders its ready queue with a min-heap even though POSIX
phrases the ordering as a maximum. aio_reqprio is a non-negative delta that can only
lower a request below its submitting thread - by itself it orders nothing, being relative
to the submitter - so the effective POSIX priority is the thread’s priority minus the
delta, and selecting the next request would take the numeric maximum of those values.
Expressed in Zephyr’s native space the same subtraction becomes
k_thread_priority_get() + aio_reqprio - one Zephyr level per unit, moving right along
the axis above - and the most urgent request is now the numeric minimum. sys_aio keys
its ready heap on that native value paired with a wraparound-safe submission sequence
number, so equal-priority requests complete first-in-first-out, as prioritized I/O
requires.
Sporadic Server Scheduling
The Sporadic Server options (_POSIX_SPORADIC_SERVER and _POSIX_THREAD_SPORADIC_SERVER)
describe the SCHED_SPORADIC scheduling policy, under which a thread runs at a foreground
priority while it has execution budget remaining, is demoted to a background priority
(sched_ss_low_priority) when the budget is exhausted, and has its budget restored through a
queue of pending replenishment operations scheduled one replenishment period after each
activation.
With the Thread Sporadic Server option
(CONFIG_POSIX_THREAD_SPORADIC_SERVER), Zephyr accepts SCHED_SPORADIC and
validates the sporadic server scheduling parameters, but does not enforce execution-time
budgets: a thread scheduled under SCHED_SPORADIC executes as if scheduled under
SCHED_RR at sched_priority. With the process-level Sporadic Server option
(CONFIG_POSIX_SPORADIC_SERVER), the same symbols become available to the
process scheduling interfaces of
_POSIX_PRIORITY_SCHEDULING:
sched_get_priority_min() and sched_get_priority_max() accept SCHED_SPORADIC, while
the process-addressed scheduling functions (sched_setparam() and sched_setscheduler())
remain stubs that fail, setting errno to ENOSYS. These deviations are denoted with the
† (obelus) wherever the options are listed.
The decision not to implement the sporadic server algorithm itself is deliberate:
- Known specification defects.
The replenishment algorithm as specified in IEEE Std 1003.1 contains well-documented defects. Under certain preemption and blocking patterns, a literal implementation of the specified rules produces premature replenishments, allowing a thread scheduled under
SCHED_SPORADICto consume substantially more processor time than its nominal budget — up to the entire processor in the worst case — thereby defeating the temporal isolation the policy is intended to provide. See M. Stanovich, T. P. Baker, A. Wang, and M. González Harbour, Defects of the POSIX Sporadic Server and How to Correct Them, in Proceedings of the 16th IEEE Real-Time and Embedded Technology and Applications Symposium (RTAS), 2010. Corrected variants exist in the literature, but they deviate from the standardized algorithm; an implementation must choose between fidelity to the specification and correct budget enforcement.- Cost imposed on the scheduler hot path.
Budget enforcement requires the kernel to maintain per-thread execution-time accounting, per-thread queues of pending replenishment operations (bounded by
sched_ss_max_repl, with merging logic when replenishments coalesce), and automatic priority switching on budget exhaustion and replenishment. Every context switch, preemption, and blocking operation touches this state. That bookkeeping conflicts with Zephyr’s goals of small, deterministic, low-overhead kernel primitives and would tax all users of the scheduler, including those who do not use the policy.- Limited adoption.
The algorithm is rarely implemented. Linux, FreeBSD, and most embedded and general-purpose operating systems omit
SCHED_SPORADICentirely; conforming applications must already handle its absence or partial support via the standard feature-test mechanisms.- Mature alternatives.
Applications requiring bounded execution or temporal isolation are better served by mechanisms that are already available and better understood:
CONFIG_SCHED_DEADLINEprovides earliest-deadline-first scheduling, the same family of algorithms adopted by Linux in preference to the sporadic server model._POSIX_THREAD_CPUTIME (
CLOCK_THREAD_CPUTIME_ID) permits per-thread execution-time measurement, and together with _POSIX_TIMERS allows an application to implement budget-monitoring policies in user space, with policy decisions (demotion, throttling, logging) tailored to the application rather than fixed by the kernel.
Multi-Process Design
This section documents the kernel and system-layer substrate that backs the
fork(), execve(), and posix_spawn families in the
POSIX_MULTI_PROCESS and POSIX_SPAWN Option Groups.
Process model
A process is a thread group: its identity is its thread-group leader, so a
process handle (k_pid_t) is a thread handle. struct k_process is the
kernel-owned record of one thread group and hangs off the leader; it is not a
handle and, except when a caller-provided record crosses the user/kernel
boundary, not a kernel object. Foreign handles are resolved by identity-value
scans under a lock and never dereferenced, so a handle stays meaningful from
creation to reap - including after the leader thread has exited. A process that
exits with children still alive hands them to init, which reaps them when they
exit; a child already dead at that point is reaped on the spot. Init’s own
direct children (static processes, the main user thread) stay zombies until
reaped, like any other child.
Numeric process, group, and session IDs are a system-layer concept, not a
kernel one: the kernel speaks only in handles, and lib/os maintains the
numbering tables behind sys_process_id() and friends. All allocation is
likewise confined to lib/os: the kernel never allocates and never calls an
allocator, only initializing caller-provided or statically defined records.
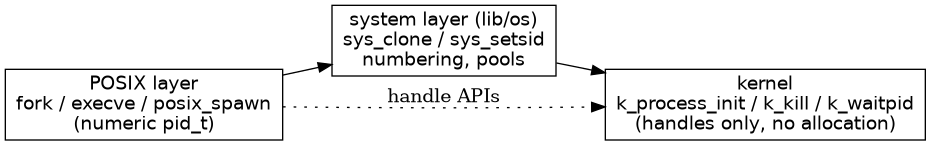
Creation: sys_clone
sys_clone() is the creation primitive; fork(), posix_spawn,
pthread_create(), and sys_thread_create() are library constructs
over it. With no flags it produces a fresh process from a
pooled record and a pool-drawn leader thread. SYS_CLONE_THREAD selects
the thread tier: the new thread joins the caller’s thread group instead -
and without CONFIG_PROCESS it is simply a new thread, so
thread creation behaves identically in process-less builds.
SYS_CLONE_PAUSED leaves the created thread stopped so a caller can apply
attributes (process group, signal mask, scheduling) before starting it.
SYS_CLONE_VM_COPY selects the fork model. Beneath the system layer,
k_clone() is the kernel primitive with the same two tiers over entirely
caller-provided memory - record, thread, and stack - allocating nothing.
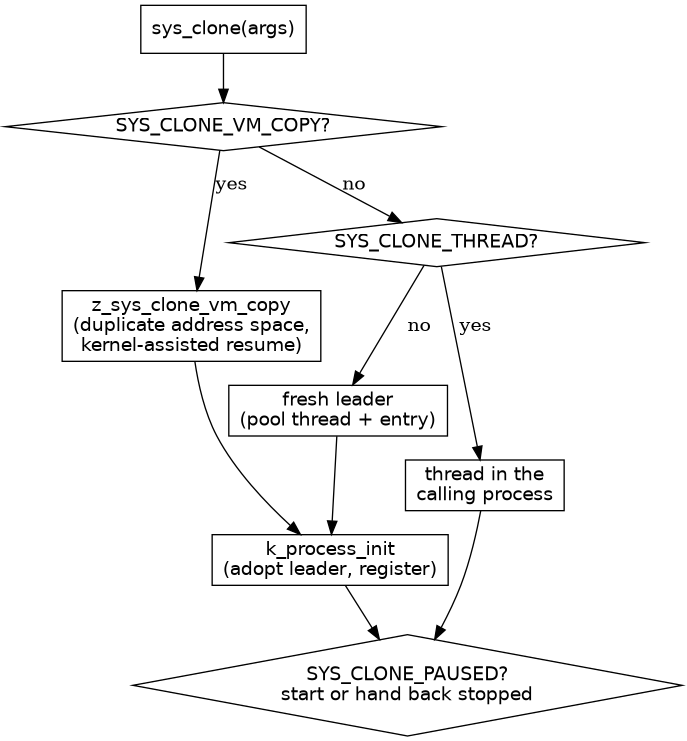
The fork model and its substrate
The fork model duplicates the caller’s writable memory into the child at
identical virtual addresses and resumes the child at the call site. Copied
memory at identical addresses is what makes the model sound where vfork
was not: the child cannot disturb the parent’s stack, and a plain
setjmp/longjmp resumes the child because every address it restores is
valid in its own copy - no architecture context-copy code is required.
The substrate is experimental (CONFIG_PROCESS_VM, x86, aarch64 and
riscv64).
process_vm_clone() builds the child’s memory domain by mirroring the
parent’s partitions, then repoints the writable ranges at fresh frames through
the architecture hook z_mem_domain_clone_remap() (no TLB shootdown, since
the child is not yet live on any CPU). The caller’s thread stack is copied only
when its user stack pointer is in it: the leader of a forked process runs on
its parent’s copied stack, and its own thread stack is just the privilege
stack of its system calls.
The copies are page frames taken from the kernel’s free frame list, not kernel heap: a process address space is sized by the memory it duplicates (a 2 MiB malloc arena per child, typically), and the kernel heap is a small fixed pool shared with everything else. The frames carry no kernel mapping. The clone fills them through a transient kernel window, mapped once per copied range in contiguous physical runs, then maps the child’s ranges at the frames run by run; the frames return to the free list when the child’s clone context is released. Because a domain’s private copies diverge from the kernel’s own mapping of the same addresses, the kernel resolves the frames behind a kernel address through its own page tables, never through the current domain’s.
The child’s resume is kernel-assisted (ARCH_HAS_FORK_RESUME, selected
by architectures providing a resume path):
the syscall entry captures the caller’s complete register state - the
callee-saved registers are saved alongside the frame precisely because the C
convention would otherwise leave a forked child with no history to restore
them from - and the child’s first run enters the common syscall exit path
from a staged copy of that frame with the return-value register zeroed. The
child’s TLS is the parent’s address: the clone already copied that region,
so captured TLS-variable addresses and register-relative accesses agree,
as fork demands. This is possible because CONFIG_PROCESS_VM excludes
CONFIG_CURRENT_THREAD_USE_TLS, leaving kernel mode with
no reason to dereference user TLS. fork() is therefore a user-mode
operation: a kernel-mode caller has no syscall frame to resume and receives
ENOTSUP; kernel-mode callers create processes with posix_spawn()
or sys_clone(), which require no duplication of the caller.
Note
Confirmed working (x86-64, x86, aarch64 and riscv64): fork() returns twice through the kernel resume, the child diverges on its own stack and data copies, and the parent - whose view is asserted unchanged - reaps it. On aarch64 no dedicated resume path was needed at all: every aarch64 thread is born through the exception return path popping a synthetic ESF, so the forked child’s birth context simply is the parent’s captured syscall frame with the return-value register zeroed. On riscv64 the kernel cannot run on the process’s page tables (S-mode cannot fetch from a user page), so a domain whose memory has diverged gets a kernel view of its own and its threads switch onto it at every trap; the resume stages the parent’s frame at the top of the child’s privilege stack and leaves through the common exception exit path.
Per-process permissions
With CONFIG_PROCESS and userspace, the process - not the
thread - is the kernel-object permission principal: threads sharing an address
space can already reach each other’s memory, so per-thread object permissions
within a process add no isolation. Each object’s permission bitmap is sized by
CONFIG_MAX_PROCESS_BYTES rather than
CONFIG_MAX_THREAD_BYTES, the principal index lives once in
struct k_process, and one sweep at reap replaces the per-thread-death walk.
Granting to any member thread grants the whole process, and a forking child
inherits the parent’s grants.
Signals
Signals are delivered either to a specific thread (pthread_kill()) or to
a process (kill(), sigqueue(), and the k_kill_all()
broadcast behind kill(-1, ...)). A process-directed signal is delivered to
one member thread that has it unblocked, preferring the caller for a
self-signal. When every member has the signal masked it pends at process
scope and is claimed by whichever member first unblocks or waits for it -
strict POSIX semantics for fully-masked processes. Kernel-resolved process
delivery bypasses the per-thread-object permission check, since kill()
authorization is process-level.
Signal dispositions are likewise a property of the process: installed by any
member thread, in force for every member, and purged when the process is
reaped. sys_clone() duplicates the parent’s dispositions into a new
process - every disposition for the fork tier, only ignored dispositions for a
fresh image (fork+exec semantics) - and execve() reverts handled
dispositions to default in place.
Exec
An exec path resolves in two tiers. First, prelinked images: a lookup
through posix_spawn_image_lookup() (a weak function applications and test
suites override). Second, with CONFIG_POSIX_EXEC_LLEXT,
real executable loading: the path is loaded from the filesystem as a linkable
loadable extension (llext), and its exported main() runs as the new
process image - the image ABI is int main(int argc, char **argv, char
**envp), and the return value becomes the process’s exit status.
Either way execve() replaces the image in place: it aborts every
other member thread with k_process_prune() and continues on the calling
thread, preserving the process’s identity, parent, and group membership;
handled signal dispositions revert to default and FD_CLOEXEC descriptors
are closed. An extension image cannot unload itself - its caller executes
from the extension - so a table sized by
CONFIG_POSIX_EXEC_LLEXT_MAX records which extension backs
which exec’d process: a main() that returns unloads in place, an image
terminated by _exit() or a signal is unloaded by the wait() family
when the process is reaped, and a chain-exec’ing image is unloaded by its
successor past exec’s point of no return. The new image then runs on the
calling thread, restarted in place. The argument
and environment vectors are staged at the top of the thread’s own stack
(sys_thread_stack_stage(), bounded by
CONFIG_POSIX_EXEC_ARG_BYTES else E2BIG - the
setup_arg_pages() analog), and sys_thread_restart() resets the
stack pointer just below them and enters the image
(arch_stack_jump(), the start_thread() analog) - same thread,
same stack, pid, signal mask, and priority all trivially preserved.
Memory protection composes per class: MMU platforms map kernel RAM
executable and PMP does not constrain machine-mode execution, so both
run images as-is; XIP MPU platforms map RAM execute-never, so under
CONFIG_USERSPACE the image’s llext partitions enter a per-image
memory domain that the exec’ing thread joins before the jump.
Remaining deviations: architectures without stack-jump support
(native_sim, whose threads run on host stacks) run the image on the
calling thread’s live frames instead, and a child that is never
collected by wait() holds its extension-table slot until the slot
is swept on a later exec.
Known deviations
The following deviations from strict POSIX are documented for
POSIX_MULTI_PROCESS and POSIX_SPAWN in the current implementation.
Each is expected to be retired as the corresponding substrate lands.
Interface |
Deviation |
|---|---|
Requires |
|
|
A path names a prelinked image or, with
|
Kernel-staged user memory in a fork child |
The kernel stages user memory through the shared kernel page tables, which map the child’s user addresses to the parent’s frames. A fork child must therefore use scalar-only system calls (no pointer copy-outs) and cannot take user-mode signal-handler delivery (the trampoline frame is kernel-staged); an inherited ignored disposition is honored, since discard happens kernel-side. Lifted when copy-outs learn to resolve through the child’s mappings. |
Signal Implementation Details
The POSIX_SIGNALS option group is implemented on top of the
kernel signal API (k_sig_*). Zephyr does not yet conventionally support interrupted or
restarted system calls. As a result, signals are delivered to a thread on its return from a
system call, so a thread that never enters the kernel does not run a signal handler
†.
Note
Efforts to support the standard behaviour (interrupting blocking system calls, with
EINTR and optional restart semantics) are underway.
abort(), raise(), and signal() are the three functions of the option group that ISO C
also requires, so they must work in a freestanding-plus-ISO-C environment where
CONFIG_POSIX_SIGNALS is not selected. They are implemented once, in the common
C library behind CONFIG_COMMON_LIBC_SIGNAL, and behave identically whichever
standard they are reached through: the calling thread is the same thread in ISO C, POSIX, and the
kernel. When the option group is linked, weak references pick up its signal number table and its
delivery shim, so signal() makes the same kernel registration sigaction() makes and a
disposition installed through either is visible to the other. Without it, only the six signal
numbers ISO C defines (SIGABRT, SIGFPE, SIGILL, SIGINT, SIGSEGV, and
SIGTERM) are reachable, and those coincide with the kernel’s numbering, so handlers take
delivery directly.
Note that only the six ISO C signal numbers can be assumed: a C library is free to number every other signal however it likes, and the numbering shipped with a given toolchain need not match the Linux-aligned numbering used by the kernel and the POSIX option group.
Process support (POSIX_MULTI_PROCESS, over the
kernel’s CONFIG_PROCESS thread-group substrate - see
Multi-Process Design) is optional, which shapes the implementation in several ways:
- Signals are process-directed or thread-directed
kill()andsigqueue()are process-directed andpthread_kill()is thread-directed. With process support, a positivepidnames a process,0the caller’s process group, a negativepidanother process group, and-1every other process (excluding the reserved system processes and the caller’s own); a process-directed signal is delivered to one member thread that has it unblocked, or pends at process scope until a member unblocks or waits for it. In a single-process configuration the process’s own pid,0, and-1all name the single (figurative) process, with the same process-directed delivery: the caller takes the signal when it has it unblocked, and it otherwise pends at system scope for the first thread that unblocks or waits for it.- Dispositions are per-process with process support
With
CONFIG_PROCESS, a signal action is a property of the process, as POSIX specifies: installed by any member thread, in force for every member, and outliving its installer. A forked child inherits every disposition, a freshly created process image inherits only ignored dispositions (fork+exec semantics), andexecreverts handled dispositions to default. Without process support the action database is keyed by (signal, thread), so an action installed by one thread is not in force for another and dies with its installer.- The interrupted context lives in the kernel, not on the user stack
A handler runs on the interrupted thread’s own stack, but the state needed to resume that thread is kept once per thread in the kernel: the return address, stack pointer and return value of the interrupted system call and the callee-saved registers, which a trampoline captures at redirection and
k_sig_return()restores. Nothing is pushed onto the user stack beyond a return address, so a delivery costs no thread stack and the kernel never allocates for it. The context is read through system calls rather than aucontext_t, and a handler cannot modify the interrupted program counter.- Handlers must not use the shared floating-point or vector registers
Nothing saves or restores floating-point or vector state around a signal handler, so a handler that uses those registers corrupts the floating-point state of the code it interrupted †. A handler confines itself to integer code, and that includes code the compiler generates: a
memcpy(),memset()or large structure assignment inside a handler may be vectorised onto those registers. Handler sources can be compiled with-mgeneral-regs-only(or the architecture’s equivalent) to rule that out.- Kernel threads block all signals by default
A kernel thread must opt in to signal delivery, with
sigprocmask()orpthread_sigmask(), before any signal can be delivered to it. User-mode threads start with no signals blocked, in line with the POSIX specification.- Faults are not signals
A CPU exception or kernel error is reported through the fatal error path rather than by generating
SIGILL,SIGFPE,SIGSEGV, orSIGBUSfor the offending thread.
Elastipool: Elastic Object Pools
Every 1:1 mapping requires a pool of kernel objects from which to allocate. Zephyr uses
elastipool (<zephyr/sys/elastipool.h>) — an elastic object pool that bridges the gap
between guaranteed static allocation and on-demand dynamic growth.
An elastipool instance is parameterized by two values:
min — the number of objects pre-allocated in a static array at compile time (guaranteed to be available, zero-latency allocation via bitmap).
max — the upper bound on total objects. When
max > min, up tomax − minadditional objects may be allocated from the heap (or other desired memory pool) at runtime.
It is useful on larger systems (e.g., those with an MMU) where the exact number of required objects is not known at compile time.
The relationship between min and max selects one of three operational modes:
Static-only pools (min == max)
When min equals max, the pool uses only statically allocated objects. No heap is required.
Allocation and deallocation are O(1) bitmap operations.

Static-only pool (min == max)
This is the most deterministic mode. It is appropriate for safety-critical or memory-constrained systems where heap allocation is undesirable or unavailable.
Dynamic-only pools (min == 0)
When min is zero, all objects are allocated from the heap. A hash map tracks outstanding
allocations so that free and check operations can validate pointers.

Dynamic-only pool (min == 0)
This mode requires CONFIG_SYS_HASH_MAP and CONFIG_SYS_HASH_FUNC32.
Hybrid pools (0 < min < max)
When both min and max are non-zero and max > min, the pool operates in hybrid
(“elastic”) mode. Allocation first attempts the static bitmap; only when the static slab is
exhausted does it fall through to the heap.

Hybrid (elastic) pool (0 < min < max)
This mode gives the best of both worlds: guaranteed availability of the first min objects with
the ability to allocate up to max.
In the threading subsystem, the pools are instantiated in zephyr/lib/os/thread.c:
K_THREAD_ARRAY_DEFINE(sys_thread_pool, SYS_THREAD_THREAD_MIN);
SYS_ELASTIPOOL_DEFINE_ADVANCED(thread_pool,
    sizeof(struct k_thread), __alignof(struct k_thread),
    SYS_THREAD_THREAD_MIN, CONFIG_SYS_THREAD_THREAD_MAX,
    thread_pool_heap_alloc, sys_thread_pool, static);
Semaphores
A sem_t is a sys_sem: a counting semaphore in the memory of the caller, usable from user
mode and shared between processes by sharing its memory (see
Process-shared synchronization). sem_post() fails with EOVERFLOW when
the count is already at SEM_VALUE_MAX (CONFIG_POSIX_SEM_VALUE_MAX); the
limit check and the increment are one atomic step on both the user-mode futex path and the
kernel path, so two concurrent posts cannot both take the last free slot. sem_wait() and
sem_timedwait() are cancellation points that test for cancellation only when they are
about to block.
Named semaphores are elastipool objects (CONFIG_POSIX_SEM_NSEMS_MAX) on a list
keyed by name, each holding a sys_sem, a reference count and a linked flag.
sem_open() reads its mode and value arguments only when O_CREAT is set. An
existing name is returned with its reference count raised and the creation attributes ignored,
unless O_EXCL is also set; value is validated only when a semaphore is created.
sem_close() accepts only a pointer returned by sem_open() and fails with
EINVAL for anything else, such as an unnamed semaphore. sem_unlink() drops the
name’s reference; the object returns to the pool when the last reference, from the name or from
an open, is gone.
Barriers
A barrier is an elastipool object holding a mutex, a condition variable, the member count, the
number of arrivals in the current cycle and a cycle number. pthread_barrier_wait()
records the cycle number on entry, under the mutex, and counts its arrival. The last arrival
advances the cycle, resets the arrival count, wakes every waiter with one broadcast and returns
PTHREAD_BARRIER_SERIAL_THREAD; every other caller sleeps on the condition variable until the
cycle number has moved on, then returns 0. Because a waiter watches the cycle number rather than
the arrival count, a thread that returns and re-enters for the next cycle cannot stall the
threads still waking up from the previous one, so a barrier can be reused immediately, as POSIX
requires. pthread_barrier_destroy() returns the object to the pool; the attribute object
holds only the pshared value.
Reader-writer locks
A reader-writer lock is an elastipool object holding an atomic reader count, a writer
semaphore, a writer gate semaphore and the owner of the write lock. Readers and writers alike
first take the writer semaphore, so a writer that is waiting keeps new readers out while it
holds it. A reader increments the reader count and, if it is the first reader, takes the writer
gate, then gives the writer semaphore back so other readers may follow. A writer keeps the
writer semaphore and then takes the writer gate, which the readers hold until the last of them
has left. The last reader decrements the count and gives the writer gate back; a new first
reader that arrives in between waits for the gate instead of assuming it is free, which closes
the window in which a writer could run beside a reader. The timed and try variants follow the
same path with a bounded or zero timeout on the writer semaphore. The attribute object holds
the pshared value.
A lock that still holds PTHREAD_RWLOCK_INITIALIZER is allocated and initialized by the first
lock call, under the pool lock, so threads racing on a statically initialized lock share one
object; pthread_rwlock_init() takes the same path.
Networking
<netinet/in.h> address tests
The IN6_IS_ADDR_*() macros take a pointer to any 16-byte IPv6 address, a POSIX
struct in6_addr of any alignment, and forward it to the Zephyr helpers behind
ZSOCK_IN6_IS_ADDR_*(), which read the bytes without alignment assumptions. The link-local and
site-local tests match the fe80::/10 and fec0::/10 prefixes of RFC 4291.
IN6_IS_ADDR_V4COMPAT() is implemented in the header itself, as Zephyr has no notion of the
deprecated IPv4-compatible form (::a.b.c.d other than :: and ::1).
Distributed Kconfig
A recurring problem in embedded systems is knowing at compile time how many of a given resource the final application will need. Different subsystems, libraries, and tests each require some number of mutexes, threads, stacks, etc.
Zephyr solves this with distributed Kconfig variables: each subsystem declares its own
CONFIG_SYS_THREAD_<POOL>_MIN_ADD_<SUBSYSTEM> symbol that contributes to the total minimum
pool size. At build time, CMake sums all _MIN_ADD_* contributions together with the base
CONFIG_SYS_THREAD_<POOL>_MIN value and emits a single SYS_THREAD_<POOL>_MIN compile
definition.
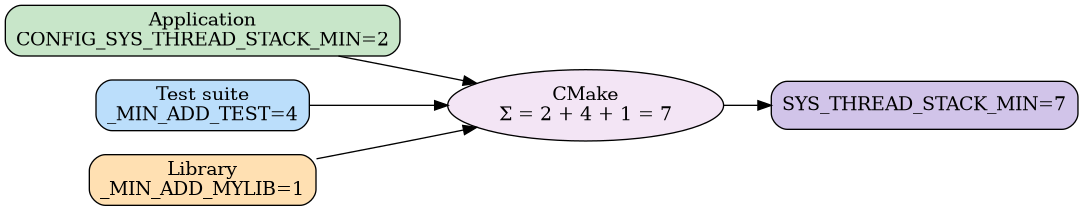
Distributed Kconfig aggregation for SYS_THREAD_STACK_MIN
The aggregation is performed by this CMake loop in zephyr/lib/os/CMakeLists.txt:
foreach(_pool STACK THREAD)
  import_kconfig(
    CONFIG_SYS_THREAD_${_pool}_MIN_ADD_
    ${DOTCONFIG}
    _sys_thread_${_pool}_min_add_keys
  )
  set(_min ${CONFIG_SYS_THREAD_${_pool}_MIN})
  foreach(_add ${_sys_thread_${_pool}_min_add_keys})
    math(EXPR _min "${_min} + ${${_add}}")
  endforeach()
  zephyr_compile_definitions(
    SYS_THREAD_${_pool}_MIN=${_min}
  )
endforeach()
The result is a non-CONFIG_ prefixed compile definition (e.g., SYS_THREAD_STACK_MIN=7)
that is used to size the static portion of the corresponding elastipool. The CONFIG_-prefixed
_MAX value (e.g., CONFIG_SYS_THREAD_STACK_MAX) sets the upper bound.
This pattern has several advantages:
Decentralized — each library or test declares exactly what it needs; no central manifest to maintain.
Additive — contributions are summed, so adding a new subsystem cannot reduce the pool below what existing consumers require.
Extensible — the same
import_kconfig/ sum /zephyr_compile_definitionspattern is already used for file descriptors (ZVFS_OPEN_ADD_SIZE_*) and is expected to expand to other bounded resources in the future.
To add a new contributor, create a Kconfig symbol in your subsystem:
config SYS_THREAD_STACK_MIN_ADD_MYLIB
    int "Thread stacks required by mylib"
    default 3
Then set it in your prj.conf or testcase.yaml:
CONFIG_SYS_THREAD_STACK_MIN_ADD_MYLIB=3
The build system automatically discovers all _MIN_ADD_* symbols and includes them in the sum.
POSIX Timers
POSIX timers map ~1:1 onto kernel timers: timer_t handles are k_timer objects
allocated from the OS-managed system timer pool (CONFIG_SYS_TIMER), armed at
full tick resolution with the clock-based kernel timer APIs
(CONFIG_TIMER_CLOCK), and validated as kernel objects in user mode - a stale
or foreign timer_t faults instead of corrupting memory.
Allocation. Applications and libraries reserve guaranteed, statically-allocated timers by
defining int Kconfig symbols named CONFIG_SYS_TIMER_MIN_ADD_<NAME>; the build system sums
them with CONFIG_SYS_TIMER_MIN. Up to
CONFIG_SYS_TIMER_MAX (default INT_MAX) timers in total may be created,
the excess allocated dynamically without guarantees; setting the maximum equal to the
accumulated minimum prohibits dynamic allocation entirely. timer_create() reports pool
exhaustion as EAGAIN.
Expiry notification is signal-based (never a callback in interrupt context, so it is
robust for user-mode callers) with POSIX one-pending semantics: at most one expiry signal per
timer is queued at a time, further expiries are accounted as overruns, and
timer_getoverrun() reads the count latched at the most recent delivery,
non-destructively, computed from the exact scheduled-expiry grid (expiries coalesced by
tickless wakeups are counted correctly). SIGEV_THREAD maps onto the kernel’s
function-notification dispatch (see k_timer_notify.fn): each expiry runs the
notification function in a fresh detached thread, as POSIX specifies, spawned by a single
kernel dispatcher woken through a reserved signal number just past SIGRTMAX that
applications can neither send, mask, nor wait on. sigev_notify_attributes are translated
at timer_create() time - stack size and priority are honored, the detach state is
always detached - and the caller may destroy the attribute object afterwards; no
per-timer allocation is made by the POSIX layer. timer_getoverrun() is valid
inside the notification function. SIGEV_THREAD_ID, the extension Linux offers under
_GNU_SOURCE, is available there as well, with one difference: on Linux
sigev_notify_thread_id carries a kernel thread ID (gettid()), whereas here it
carries a pthread_t value. A NULL evp behaves as POSIX specifies: SIGEV_SIGNAL with
SIGALRM and the timer ID as the value.
Clocks. TIMER_ABSTIME deadlines are honored on both CLOCK_MONOTONIC and
CLOCK_REALTIME; with CONFIG_TIMER_REALTIME (selected by
CONFIG_POSIX_TIMERS), armed absolute CLOCK_REALTIME timers are
re-targeted when clock_settime() moves the wall clock - a forward jump past the
deadline fires the timer immediately, a backward jump defers it. Re-targeting applies to the
initial expiry only; afterwards a periodic timer’s interval continues on the monotonic grid,
matching Linux.
Reduced mode. When signal-based expiry notification
(CONFIG_TIMER_SIGNAL) is unavailable, SIGEV_NONE timers remain fully
functional as time sources, while SIGEV_SIGNAL, SIGEV_THREAD, and
SIGEV_THREAD_ID report ENOTSUP from timer_create() (SIGEV_THREAD
additionally requires the system thread pool, CONFIG_SYS_THREAD with
CONFIG_THREAD_DETACH). Every AEP profile enables the signal subsystem
by default.
Migration from earlier releases: CONFIG_POSIX_TIMER_MAX (still reported by
TIMER_MAX and sysconf(_SC_TIMER_MAX)) is no longer user configurable - it is derived
from CONFIG_SYS_TIMER_MAX, which bounds the pool; guaranteed capacity moved
to the distributed CONFIG_SYS_TIMER_MIN_ADD_<NAME> minimum, and
CONFIG_TIMER_CREATE_WAIT was removed because timer_create() no longer blocks.
POSIX Message Queues
POSIX message queues map 1:1 onto kernel message queues: a queue is a k_msgq
object allocated from the OS-managed system message queue pool
(CONFIG_SYS_MSGQ), and mqd_t is a file descriptor naming it. Every
mq_*() call is one system call plus errno translation, so the whole option group is
usable from user mode: no kernel object pointer is ever exposed, and a stale or foreign
descriptor reports EBADF instead of corrupting memory.
Allocation. Applications and libraries reserve guaranteed, statically-allocated queues by
defining int Kconfig symbols named CONFIG_SYS_MSGQ_MIN_ADD_<NAME>; the build system sums
them with CONFIG_SYS_MSGQ_MIN. Up to CONFIG_SYS_MSGQ_MAX
(default INT_MAX) queues may exist, the excess allocated dynamically without guarantees;
setting the maximum equal to the accumulated minimum prohibits dynamic allocation entirely.
Statically allocated queues draw message storage from a fixed per-queue budget
(CONFIG_SYS_MSGQ_BUF_SIZE) and mq_open() reports a geometry that
does not fit as ENOSPC; dynamically allocated queues size their storage to the request and
are not bound by that budget. Queue names are at most
CONFIG_SYS_MSGQ_NAMELEN_MAX characters.
Messages carry a priority and a length. mq_send() orders messages by descending
priority, FIFO within a priority, and mq_receive() reports the priority of the message
it returns along with its actual length - messages shorter than mq_msgsize are delivered
as sent, not padded. Priorities range from 0 to
CONFIG_POSIX_MQ_PRIO_MAX - 1 (reported by MQ_PRIO_MAX).
Descriptors. The access mode and O_NONBLOCK are per open file description, as POSIX
specifies: two descriptors for one queue may differ in both, and mq_setattr() changes
O_NONBLOCK for the calling descriptor alone. A queue persists after its last descriptor is
closed and is destroyed only once it has been unlinked and no descriptor remains; the name is
released immediately by mq_unlink(), so it may be reused for a new queue while the old
one is still being drained. Both timed calls take absolute CLOCK_REALTIME deadlines,
report expiry as ETIMEDOUT, and are distinguished from a non-blocking descriptor’s
EAGAIN.
Notification. mq_notify() supports SIGEV_NONE, SIGEV_SIGNAL,
SIGEV_THREAD, and (under _GNU_SOURCE) Linux’s SIGEV_THREAD_ID extension
(carrying a pthread_t rather than Linux’s kernel thread ID). The
registration is armed in the kernel, so the empty-to-non-empty transition is detected
atomically with the send rather than by sampling the queue depth around it; it fires exactly
once and is consumed as it fires, after which a new registration may be armed. Arming while
one is already armed reports EBUSY; removing one that was never armed succeeds, matching
Linux. SIGEV_SIGNAL targets the registering thread rather than the process
† and delivers si_code SI_MESGQ. SIGEV_THREAD maps onto the kernel’s function
notification dispatch (see sys_msgq_notify.fn): each arrival runs the
notification function in a fresh detached system-pool thread, spawned by a kernel dispatcher
woken through a reserved signal number past SIGRTMAX that applications can neither send,
mask, nor wait on - notification threads for registrations made by user threads run in user
mode, in the registrant’s memory domain, with the registrant’s object permissions.
sigev_notify_attributes are translated at registration time - stack size and priority are
honored, the detach state is always detached - and the caller may destroy the attribute
object afterwards; no POSIX-side state or service thread is involved, so every notification
form works from user mode.
Migration from earlier releases: mqd_t is now an int file descriptor rather than an
opaque pointer, so a failed mq_open() compares against (mqd_t)-1 and descriptors
count against the ZVFS descriptor table
(CONFIG_ZVFS_OPEN_ADD_SIZE_SYS_MSGQ). mq_receive() and
mq_timedreceive() return ssize_t, as POSIX specifies.
CONFIG_POSIX_MQ_OPEN_MAX, CONFIG_MSG_SIZE_MAX, and
CONFIG_MQUEUE_NAMELEN_MAX are no longer user configurable - they derive from the
corresponding SYS_MSGQ bounds.
POSIX Asynchronous I/O
Asynchronous I/O is a thin veneer over sys_aio, an OS-managed pool of asynchronous I/O
requests (CONFIG_SYS_AIO) performed by a dedicated kernel service queue.
aiocb carries the request handle, and every aio_*() call is one system call
plus errno translation - no POSIX-side request state or service thread exists - so the
whole option group works from user mode. Handles are validated by pool membership on every
call: a stale or foreign handle reports EINVAL instead of corrupting memory.
Dispatch. Submission classifies the descriptor once: descriptors with a waitable
readiness condition (sockets, eventfds) are armed on ZVFS_POLLIN/ZVFS_POLLOUT
readiness with a triggered work item over the events their backend registers for
poll(), so no thread parks while a request waits; always-ready descriptors (regular
files - see below), already-ready ones, and offloaded sockets execute directly on the
service queue thread. Operations execute one at a time in completion order
(CONFIG_SYS_AIO_WORKQ_PRIO,
CONFIG_SYS_AIO_WORKQ_STACK_SIZE): a slow operation delays those queued
behind it, the file-system driver runs on the service queue’s stack, and a request whose
readiness regresses between the wakeup and the transfer may briefly block the queue. This
dispatcher is deliberately a small internal seam: a future backend with uniform,
driver-level asynchronous submission can replace it without changing the system call
contract or the POSIX layer above it. Connecting POSIX asynchronous I/O to RTIO is in the early planning stages - RTIO would first need to express operations on
integer file descriptors and file offsets (today its submissions address iodev objects
with no offset field), possibly by way of a posix_devctl()-style uniform device
interface.
As a prerequisite, poll() was taught that descriptors whose backends have no poll
support - regular files, shared memory, message queues, and the standard streams - are
always ready for input and output, as POSIX requires of regular files, rather than failing
with an unspecified error.
Completion is recorded in the request and is sticky: aio_error() reports
EINPROGRESS until the operation finishes, aio_suspend() waits any-of on
per-request completion signals (at most CONFIG_SYS_AIO_WAIT_MAX entries),
and aio_return() reaps the request, returning its slot to the pool. Closing a
descriptor with requests in flight completes them with EBADF: the service queue
re-validates the descriptor’s backing object before every transfer. aio_cancel()
removes armed and queued requests race-free - a claimed request completes with
ECANCELED, wakes waiters, and still fires its notification - and reports
AIO_NOTCANCELED for one already executing.
Notification mirrors the message queue model: SIGEV_SIGNAL generates the signal
kernel-side with an SI_ASYNCIO code (the target is validated at submission, so no
sender permissions apply at completion time), and SIGEV_THREAD runs the notification
function in a fresh detached system-pool thread - in user mode, in the submitter’s memory
domain, when the request was submitted from a user thread. Completion groups back
lio_listio()’s LIO_NOWAIT list notification: each submission joins the group,
and the group’s single notification fires the moment its last member completes, after which
the group destroys itself.
Allocation follows the distributed-minimum idiom shared with sys_thread,
sys_timer, and sys_msgq: CONFIG_SYS_AIO_MIN_ADD_<NAME> contributions are summed
with CONFIG_SYS_AIO_MIN into a statically allocated, guaranteed pool
minimum, with CONFIG_SYS_AIO_MAX bounding the heap-allocated remainder.
AIO_MAX and AIO_LISTIO_MAX derive from those bounds
(CONFIG_POSIX_AIO_MAX, CONFIG_POSIX_AIO_LISTIO_MAX).
aio_fsync() synchronizes data and metadata together: O_DSYNC and O_SYNC are
equivalent.
Prioritization: with CONFIG_POSIX_PRIORITIZED_IO (enabled by default;
selects CONFIG_SYS_AIO_PRIORITY), _POSIX_PRIORITIZED_IO is defined and
the service queue performs ready requests in priority order from a min-heap rather than in
submission order: each request is ordered by the calling thread’s scheduling priority lowered
by aio_reqprio (0 through AIO_PRIO_DELTA_MAX, one Zephyr priority level per unit),
first-in-first-out among equal priorities, for every descriptor served by the request pool.
Scheduling Priorities explains why that ordering is a min-heap in Zephyr’s
native priority space.
When disabled, AIO_PRIO_DELTA_MAX is 0, aio_reqprio must be 0, and ready requests
are performed in submission order.
File System Implementation Details
The POSIX_FILE_SYSTEM option group is a thin layer over
the Zephyr Virtual File System (ZVFS) and, through it, the file system API.
Path, directory-stream, and working-directory operations are ZVFS system calls, so the whole
option group works from user mode when CONFIG_USERSPACE is enabled.
ZVFS is the common waypoint for every file-descriptor consumer. The POSIX file API and the C
library’s <stdio.h> both bottom out in the same ZVFS entry points - fopen() and
open() are two spellings of zvfs_open() - so an application reaches one file system
implementation whichever interface it uses.
Timestamps through a descriptor. futimens() resolves the UTIME_NOW and
UTIME_OMIT markers against CLOCK_REALTIME and the descriptor’s current times, then sets
them with one ZVFS call, zvfs_futime(): the ZFD_IOCTL_UTIME request on the open object,
which the file and directory objects answer with fs_utime() on their retained path. The same
objects fill the timestamps for fstat(), so what a descriptor sets a descriptor reads back,
and the function works from user mode like the rest of the group. Which timestamps a backend
records is the file system’s business: see Timestamps below.
The root is not a file system but a directory of mount points: statvfs() of "/"
(and fstatvfs() of a descriptor of it) reports a read-only (ST_RDONLY) pseudo file
system with 4096-byte blocks and none of them, one file per mount point, and the file-name
maximum. Record locks (fcntl() with F_SETLK, F_SETLKW and F_GETLK) are kept
by ZVFS as unsigned 64-bit ranges; struct flock carries the POSIX off_t fields, so a
region before its reference point (a negative l_start or l_len) is rejected with
EINVAL and a lock that does not fit off_t on the way out of F_GETLK is EOVERFLOW.
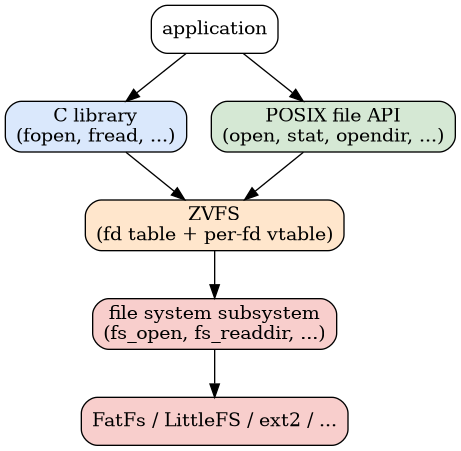
libc and the POSIX API both reach the file system through ZVFS
The file system is only one of several descriptor types ZVFS multiplexes. Every open descriptor
is a slot in the ZVFS fd table carrying a vtable; a read, write, or ioctl on the descriptor
dispatches through that vtable to the owning backend, so the same read()/write()/
close()/poll() reach a regular file, a socket, an eventfd, or a message queue without the
caller knowing which.
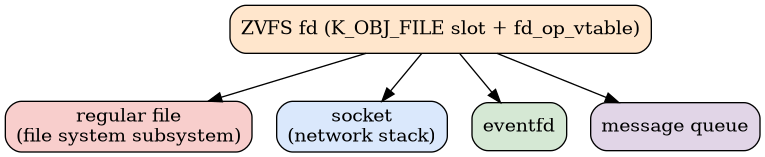
A ZVFS descriptor dispatches through its vtable to one of many backends
Zephyr kernel caveats
These reflect the Zephyr kernel model rather than the file system.
- Working directory
ZVFS keeps the current working directory per process. A child created by
fork()orposix_spawn()starts with a copy of its parent’s, achdir()in one process is invisible to every other, and the directory survivesexecve(), as POSIX requires. Threads that belong to no process - every thread whenCONFIG_PROCESSis off - share the boot directory, which is the POSIX per-process model on a single-process system. Every path operation resolves its argument against it, so relative paths work throughout - including through ISO Cfopen()and POSIXopen(), which share the same ZVFS entry point.chdir(),fchdir(), andgetcwd()read and update it. Resolution is purely lexical:.,.., and repeated separators are collapsed without consulting the file system. On a backend that supports symbolic links (such as ext2) this is a simplification - full POSIX pathname resolution would resolve a..component relative to the target of a preceding symbolic link, whereas lexical resolution collapses it textually.- Temporary files
tmpfile()andtmpnam()are provided by the common C library (CONFIG_COMMON_LIBC_TMPFILE) for every libc, and require/tmpto exist on a mounted file system. ISO C removes thetmpfile()stream when it is closed or at normal program termination; the file is removed on the final close of its descriptor -fclose(), or the descriptor sweep at process exit when process support (CONFIG_PROCESS) is enabled. Without process support a stream that is never closed leaves its file in place, as there is no process termination at which to remove it.
Zephyr FS subsystem caveats
Because the POSIX layer is thin, its capabilities track the Zephyr FS subsystem - the
fs_* API and its fs_file_system_t back-end interface - rather than the on-disk features
of any particular file system. The deviations below are gaps in what the subsystem exposes, not in
the POSIX code or the backing file system; when the subsystem grows an operation, the POSIX layer
surfaces it with little or no change.
- No hard links
The Zephyr FS subsystem exposes no hard-link operation, so
link()always fails withEPERM- which POSIX permits for an implementation that prohibits the operation - andst_nlinkis always 1. This is a subsystem limitation, not a file system one: ext2, for example, stores hard links on disk, but the subsystem offers no way to create or count them.- No symbolic links
The subsystem exposes no symbolic-link operations, so path resolution never follows a symlink and stays purely lexical (see Working directory above). As with hard links this is a subsystem limitation, not a file system one - ext2 stores symbolic links on disk, but the subsystem offers no way to create or read them.
- Permission bits are not exposed
The subsystem’s
struct fs_direntcarries no mode bits, sostat()cannot report a file system’s stored permissions even when it has them - ext2 again being the example. It reports a synthesised mode instead: read and search for everyone, plus write unless the mount is read-only.access()andmkdir()follow suit -mkdir()accepts itsmodeargument and ignores it, andaccess()grantsX_OKonly for directories.- Timestamps
File timestamps are surfaced only when the backend records them, gated by
CONFIG_FS_DIRENT_EXT. Where a backend stores no timestamps,fs_utime()returns-ENOTSUP- whichutime()surfaces aserrnoENOTSUP- andstat()reports zero forst_atim/st_mtim/st_ctim(the subsystem clears the fields before asking the backend). No backend keeps a status-change time, sost_ctimrepeatsst_mtim. Per-backend behaviour is noted under the file-system-specific caveats below.
FAT-specific caveats
FatFs (the ELM ChaN library behind CONFIG_FAT_FILESYSTEM_ELM) predates and
ignores POSIX naming conventions, which leaks through the abstraction in a few ways worth knowing
when FatFs is the backend.
- Type-name collision with
<dirent.h> FatFs declares its public types with unprefixed names -
DIR,FIL,FATFS,FRESULT- inff.h.DIRcollides with the POSIXDIRfrom<dirent.h>, so a single translation unit cannot include bothff.h(needed to declare aFATFSmount object, for example) and<dirent.h>. Code that mounts a FAT volume and walks directories with POSIXopendir()/readdir()must split those uses across separate translation units, or use thefs_*directory API on the FatFs side. This is a namespacing defect in the FatFs module, not in the POSIX layer, but the POSIX layer inherits the constraint.- Short file names
Without
CONFIG_FS_FATFS_LFN, FatFs is limited to 8.3 short names, sopathconf(_PC_NAME_MAX)reports 12 and longer names fail. Short names are stored upper-cased, soreaddir()returnsFILE.TXTfor a file created asfile.txt.- Coarse, modification-only timestamps
FAT records a single modification time with two-second granularity and no access time, so
st_atimmirrorsst_mtimandpathconf(_PC_TIMESTAMP_RESOLUTION)reflects the coarser value. Timestamp writes additionally requireCONFIG_FS_FATFS_FF_USE_CHMOD.- Non-canonical
errnovalues FatFs maps several conditions onto
errnovalues that differ from the POSIX-preferred spelling: opening a non-directory as a directory reportsENOENTrather thanENOTDIR, and removing a non-empty directory reportsEACCESrather thanENOTEMPTY. Tests that assert these paths accept either spelling.- rename() is not an atomic replace
FatFs
rename()fails withEEXISTwhen the target already exists, rather than atomically replacing it as POSIX requires.
LittleFS-specific caveats
ext2-specific caveats
Among the in-tree backends, ext2 is the notable case where the on-disk format does support the features the Zephyr FS subsystem withholds. The limitations in Zephyr FS subsystem caveats above therefore still apply to ext2, even though the volume itself could satisfy them:
- Hard links are not supported
link()fails withEPERMandst_nlinkis always 1, though ext2 stores hard links on disk.- Symbolic links are not supported
Symbolic links are neither created nor followed, though ext2 stores them on disk.
- Permissions may not be reported accurately
stat()reports a synthesised mode rather than the file’s stored permission bits.
Memory-Mapped Files
The POSIX_MAPPED_FILES and
POSIX_MEMORY_PROTECTION option groups are thin layers
over four ZVFS system calls: zvfs_mmap(), zvfs_munmap(), zvfs_msync(), and
zvfs_mprotect() (CONFIG_ZVFS_MMAP). The POSIX functions convert their
PROT_*, MAP_*, and MS_* arguments to the ZVFS flag namespace and return the result;
everything else, including the mapping registry, lives in ZVFS, so mappings work from user mode
when CONFIG_USERSPACE is enabled.
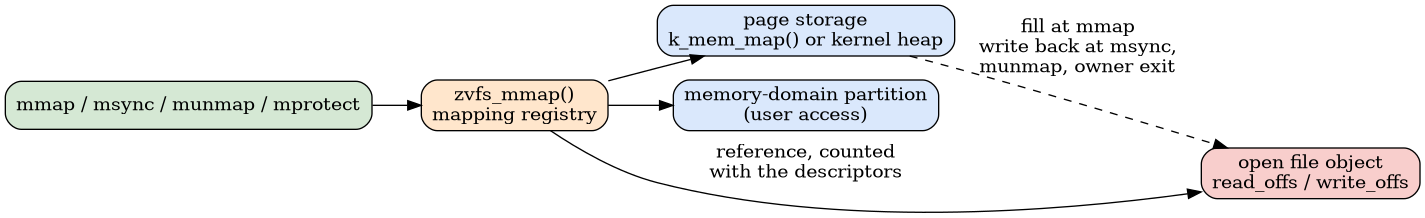
a mapping is a registry record over page storage and a referenced open file
- Storage
With an MMU (
CONFIG_MMU), a mapping owns anonymously mapped pages fromk_mem_map(), with guard pages on both sides. The pages are pinned: underCONFIG_DEMAND_PAGINGa lazily backed page would come into existence in the kernel’s page tables only, on first touch, and the memory domains that map it would never see it. Pinning also makes every mapping trivially satisfymlock(). Without an MMU, a mapping owns a block of the kernel heap at a 64-byte granule (CONFIG_ZVFS_MMAP_PAGE_SIZE, whichsysconf()reports as_SC_PAGESIZE). Lengths and file offsets are rounded to that granule.- File contents
A file-backed mapping is a copy: the pages are filled from the file when the mapping is created (bytes past the end of the file within the last page read as zero) and, for a
MAP_SHAREDmapping that has been writable, written back onmsync(), onmunmap(), and when the owner exits. Write-back is clipped to the file’s size at that time, so writing through a mapping never grows the file. WithCONFIG_ZVFS_MMAP_DIRTY_TRACK(an MMU whose fault handler offers write faults to the kernel) the pages of a shared writable mapping start write-protected: the first write to a page faults, the page is recorded as modified and made writable, andmsync()writes back only the modified pages before protecting them again, so a page changed through the descriptor in the meantime is not overwritten by a stale copy.MS_INVALIDATEwrites the range back, re-reads it, and re-reads the same range of every other mapping of the same file (through any descriptor), so mappings see one another’s synchronized stores as they would through a shared page cache. Without it the whole range is written back.MS_INVALIDATEre-reads the pages from the file. Two mappings of the same file are therefore coherent only throughmsync(); there is no page cache. A mapping counts as a reference on the open file object alongside its descriptors, so the file stays open afterclose()until the last mapping of it is released.- Objects that own their pages
A file object that already has pages of its own answers
ZFD_IOCTL_MMAPwith their address, and the mapping refers to those pages in place. Shared memory objects (shm_open()) work this way, so every mapping of one object aliases the same memory, from kernel and user mode alike; as such mappings share their address,munmap()on it releases them all.- Protection
A user thread reaches a mapping through a memory-domain partition on its pages, added to the caller’s domain when a user thread creates the mapping (or later changes its protection) and removed when it is unmapped. Each mapping is one partition, so the number a user thread can hold at once is bounded by the domain’s free partition slots. On MPU platforms the mapping’s storage is a power-of-two block aligned to its size, as the protection regions require, and the calling thread’s regions are reprogrammed before the system call returns, since Cortex-M otherwise applies domain changes only at the next context switch. The kernel’s own view of the pages it owns follows the protection too, but supervisor-mode enforcement is a property of the architecture, not of the API: only user-mode accesses are guaranteed to fault.
- Shared memory objects
shm_open()andshm_unlink()are thin over thezvfs_shm_open()andzvfs_shm_unlink()system calls (CONFIG_ZVFS_SHM), so they work from user mode. An object is a named, system-wide entry in a pool ofCONFIG_ZVFS_SHM_MAX, compared by name (not by hash), sized once withftruncate(), read and written at offsets, and mapped in place: it owns pinned pages (a power-of-two heap block without an MMU) and hands their address to the mapping layer, so everymmap()of it aliases the same memory andmunmap()on that address releases all of them.shm_unlink()removes the name at once, a latershm_open()withO_CREATcreates a fresh object under it, and the unlinked object is freed when its last descriptor and its last mapping are gone. Resizing a sized object andO_TRUNCon it fail withEBUSY, since its pages may be mapped; there are no per-process permissions, somodeis recorded but not enforced.- Ownership
A mapping belongs to the thread that created it or, with
CONFIG_PROCESS, to that thread’s process, and the mapping functions only reach the caller’s own process’s mappings. When the owner exits its mappings are torn down: shared file mappings are written back and every mapping is unmapped. A process that exits through_exit()does this in its own context, so the file is current by the time the process can be waited for; a thread, or a process whose last thread simply returns, leaves the work to the next mapping operation, because the exit path itself cannot block.msync()remains the only way to guarantee that modifications have reached the file at a given point.- Inheritance
A child created with a copy of its parent’s address space (
CONFIG_PROCESS_VM) inherits the parent’s mappings:MAP_SHAREDmappings keep referring to the same pages, so writes are visible across the two processes and either maymsync()them, whileMAP_PRIVATEmappings are copied like the rest of the writable memory. Each side unmaps independently; the pages and the file reference go with the last of them. A child started on a new image has no mappings.- Deviations
MAP_FIXEDis not supported (ENOTSUP); the address hint is ignored.munmap()of part of a mapping trims it or splits it into two pieces that share the original’s storage, which is released with the last piece; a mapping shared with forked copies, or granted to user mode on a board without an MMU (its protection region covers it whole), keeps its shape and fails withEINVAL.mprotect()operates on whole mappings: a range covering part of one fails withENOTSUP. Writable and executable pages are never granted together (ENOTSUP). A reference past the end of the file beyond the last mapped page cannot raiseSIGBUS; the page is simply not mapped.
Memory Locking
mlock(), munlock(), mlockall() and munlockall() are thin over
the zvfs_mlock() and zvfs_munlock() system calls (CONFIG_ZVFS_MLOCK),
so they work from user mode and validate their arguments in the kernel. A locked page is
resident and exempt from eviction, which only means something under
CONFIG_DEMAND_PAGING: without it every page is resident already, and all four
validate their arguments and succeed without effect.
- Ranges
mlock()andmunlock()round the range to pages and pin or unpin them with the kernel’s demand paging API. A user thread may only lock memory it can read: anything else, like a range outside memory, is not memory the process has and fails withENOMEM. A range that wraps fails withEINVAL. A length of zero does nothing.- Whole address space
MCL_CURRENTlocks the caller’s mappings and, from user mode, every partition of its memory domain, which is the memory a thread of the process can reach.MCL_FUTUREis a per-process flag (the kernel’s own threads share one) that makes every mapping created from then on locked at creation;munlockall()clears it and unlocks the same set. The flag is not inherited by a child process.- Mappings
The pages of a mapping are pinned for its lifetime, as Memory-Mapped Files describes, so locking them changes nothing and unlocking passes over them: a range or a partition that covers a mapping is unlocked around it. Locking is a property of pages, not of the process: pages shared with another process through a partition are locked and unlocked for both.